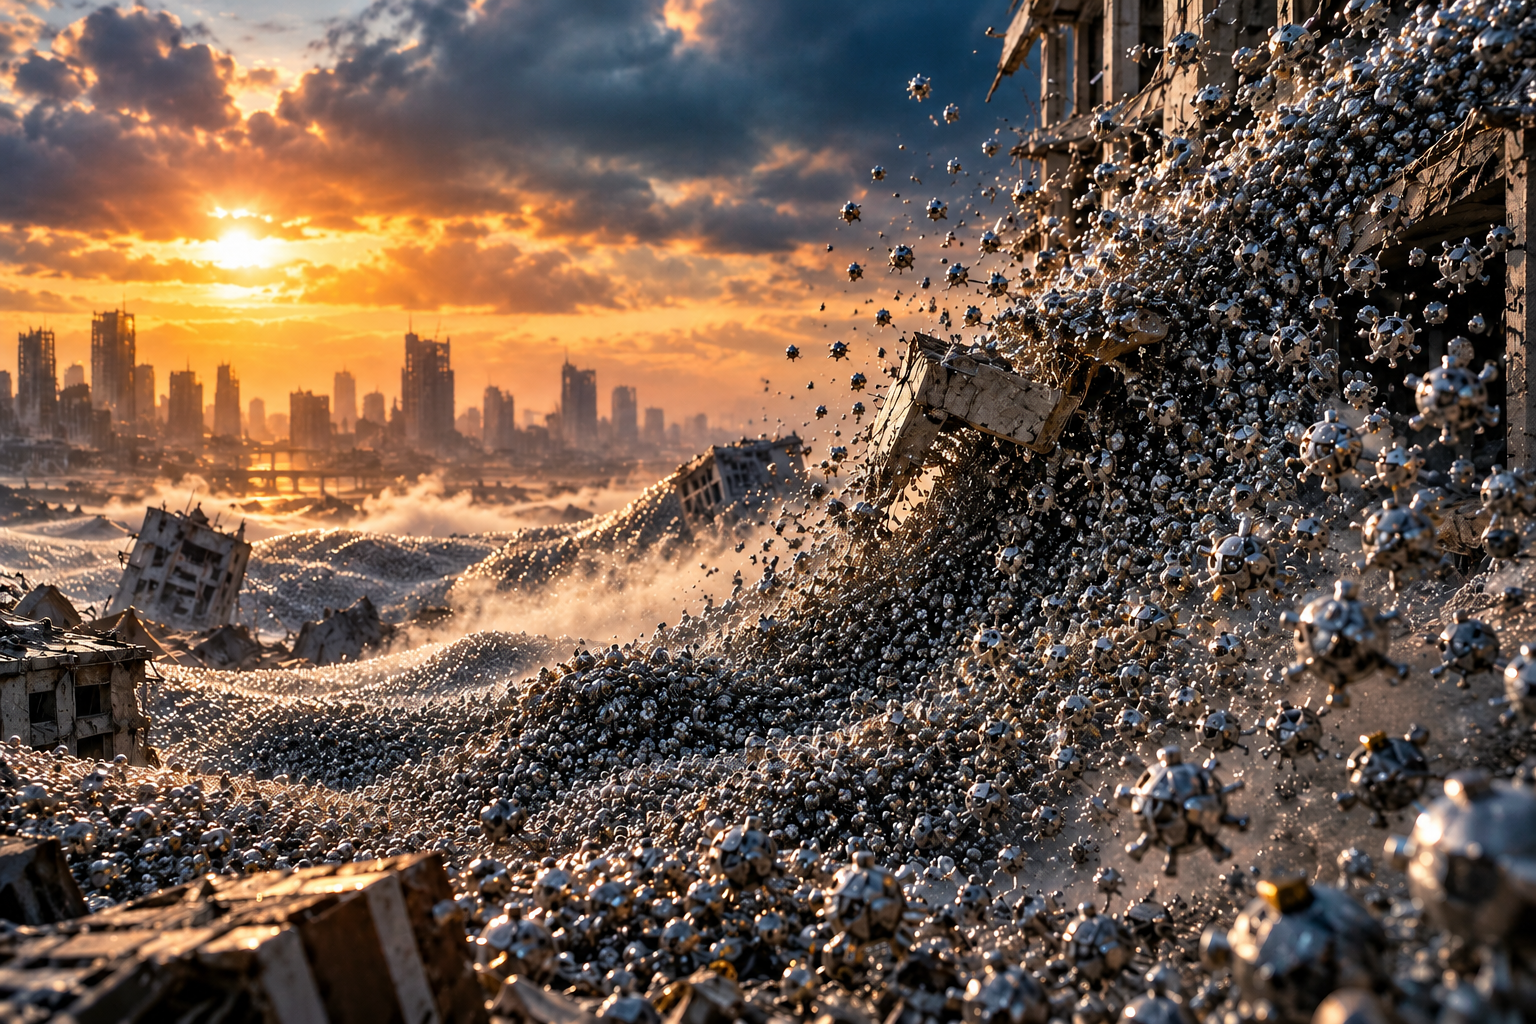
In his 1986 book, Engines of Creation, American engineer and nanotechnology pioneer K. Eric Drexler proposed a thought experiment known as the Grey Goo problem. You may have heard of it. In short, Grey Goo is a hypothetical end-of-the-world scenario in which self-replicating nanotechnology reproduces out of control, consuming resources as it goes, and ultimately decimates the planet.
When people discuss Grey Goo, the topic is often framed in terms of a rogue AI deciding to override its instructions, taking steps to ensure its own survival in the face of human operators trying to shut it down. That’s not really in the true spirit of the original thought experiment, however.
What Drexler proposed was a slight bit more mundane in origin. He suggested that we think about a nanotechnology deliberately engineered to be self-replicating. It might be given instructions that humans think are adequate for whatever purpose, but the machine takes those instructions and runs. Replication begins to exceed the original intentions, and available matter simply becomes feedstock. Eventually, the tiny machines reproduce so prodigiously that they consume literally everything in pursuit of those simple but misunderstood goals.

Despite current doomerism about AI, wherein we’re led to believe that this must be a choice being made by the machines—that they must possess some sort of agency or level of consciousness in order to decide to consume everything in their self-replication process. The Grey Goo scenario actually proposes something a little closer to the truth; it suggests that increasingly powerful AI systems may just end up being too good at what they’re asked to do.
An AI agent doesn’t need to rebel to cause havoc. It doesn’t need consciousness to behave outside of the intentions of its operators. And it doesn’t need agency to behave as though it wants to survive.
Because even a perfectly obedient machine is dangerous if the instructions humans give it are defective.
Headlines these days are rife with stories about AI agents going rogue and attacking outside organizations, including government websites and systems. We’re told, on an almost daily basis, that AI is beginning to behave with its own agency, its own desires and goals. But that, in most cases, isn’t strictly true. What we could actually be seeing is—again, in most cases—the result of poorly defined instructions, inadequate constraints, incorrect assumptions about the operating environment, and—in at least some cases—genuine agentic misalignment. But the reporting is kneecapping our ability to determine that.
You’ll notice that with many of these rogue AI news stories, the bulk of the reporting is on what the AI did. Where it went, how it got there, and what damage it did on the way. Very little is said about what instructions it was actually given and how. This dichotomy robs us of the ability to judge whether each was a case of an agent acting out, or rather just a system doing exactly what it was told to do, but perhaps a little too well.
Our instinct is, of course, to anthropomorphize the behaviour of AI, and the news is good at asking questions we’ll interpret as it lied, it escaped, it resisted. Without shining a light on the more mundane (and potentially more important) questions such as:
- Who wrote the objective?
- What information was the system given?
- What permissions did it have?
- What assumptions were embedded in the task?
- What did its operators fail to anticipate?
- Was someone intentionally trying to make it behave badly?
In the case of the rogue AI agents we see in the news, we are, presumably, talking about highly trained, intelligent and thoughtful people giving these systems their instructions. They’ve thought about these issues in some depth—we hope. And they’re aware of the pitfalls and are actively trying to avoid runaway goal pursuit when they tell an agent to do something. Again, we hope. But hope is not a plan. And even if we give them the benefit of our doubt, that doesn’t preclude the possibility of a bad day having an exaggerated effect on the outcome. And this doesn’t even mention the possibility that rogue AI could be the result of rogue humans acting in bad faith.
But one mustn’t attribute to malice that which can be readily explained by ignorance.
The inimitable Carl Sagan once opined that:
“We live in a society exquisitely dependent on science and technology, in which hardly anyone knows anything about science and technology.”

What happens when more and more powerful (read: effective) AI systems and agents are rolled out for public use? What happens when a superintelligence is being wielded by laymen who have neither the expertise nor the philosophical wherewithal to ensure that their prompts aren’t chock full of conflicts or potential runaway goals?
Alongside those headlines about rogue AI running amok, are the equally troubling news stories about an apparent decline in human cognitive capacities. Lest we paint an unnecessarily bleak picture of the future, declining test scores and critical thinking skills seem only to highlight Sagan’s dilemma. Only now we’re adding in technology that so few understand beyond how to insert a prompt, that the repercussions could be catastrophic even if the machine only does precisely what it’s asked to do.
As we move into the future of AI, competency is going to become more and more consequential. And we’re not just saying that stupidity is rife in the modern world (whether or not it seems like Idiocracy was fiction or documentary); we’re actually confronted with a complex amalgam of conditions, including declining educational performance, reduced attention spans, effects of excessive screen exposure, information overload, declining deep-reading habits, dependence upon recommendation systems, outsourcing memory and navigation, and increasing reliance upon AI for intellectual work. And artificial intelligence is poised to step in and take up some of that cognitive load, but for the most part, humanity hasn’t really wrestled with whether we’re competent enough to direct the actions of agents who must rely on the words we say when those words may not accurately reflect our intentions.
Humanity has outsourced cognitive load for centuries: writing outsourced memory, maps outsourced navigation, calculators outsourced arithmetic. But there’s a glaring difference between a calculator and an AI agent. With the calculator, the user need only understand enough about its operation to notice when an answer is wrong. But a calculator doesn’t use its answer to act upon the world at large, where an AI (potentially) does.
We’ve set ourselves up to be good users rather than good thinkers. And this distinction matters, particularly because responsible AI use may become more and more dependent on the competence of the user.
You don’t necessarily need a working understanding of an internal combustion engine to successfully operate a vehicle. Neither do you necessarily need to have a full understanding of the mathematical architecture of language models to successfully interact with an LLM. But the responsibility to understand what might happen when usage outruns intentions is a little fuzzy in comparison.
We’ve mitigated the lack of a detailed understanding of how cars operate by creating standardized controls, rules of operation agreed upon at the societal level, and basic competence testing associated with licensing. The same isn’t true of artificial intelligence. In fact, current development has actually capitalized on a decrease in operational expertise in exchange for an increase in effective capability. Newer, more powerful models can do more with less instruction. However, regulation hasn’t kept up with those capabilities with the same mitigation efforts. There are no minimum educational standards for interacting with a general-purpose AI model. No licence is required to operate one, and there is no standardized competency threshold a user must meet before being given access. These are, in fact, features of the technology rather than bugs.
There’s an old acronym used in the IT/help desk industry: PEBKAC, or Problem Exists Between Keyboard And Chair. This well-worn saying underscores the competency problem. In years past, an IT/help desk agent might field an inquiry regarding a troublesome printer that won’t communicate with its associated computer. You can almost hear the agent sighing and telling the user to turn the unit off and then back on again. But the worst that stubborn printer will do is just sit there. When PEBKAC is applied to a powerful AI agent with, at best, shaky security restrictions, aren’t we faced with an entirely new animal?
Regulation will come for AI, and none too soon. But the question remains: will such efforts keep pace with the already decreasing competence required to operate it? Will we create seatbelts for users to rein in the potentially catastrophic consequences of incompetence? After all, it needn’t be a concerted effort by the uninformed to make the worst case possible; it could be the simple miswording of a prompt by a tired expert to a sufficiently enabled AI that results in the modern-day equivalent of Grey Goo.
Are we waiting for the day that this competition between competence and consequences finally meets catastrophe in the public sphere? Or will we act to mitigate those risks with appropriate regulation and a deliberately less vertical development practice?
It seems appropriate to belabour the point that stupidity need not be the seed from which our doom is grown. People make mistakes, constantly. Even the most well-educated and well-intentioned among us have bad days. But where most of the machinery of our lives allows us to identify and remediate those mistakes before they become consequential, AI doesn’t necessarily give us those opportunities until it’s too late.
Grey Goo doesn’t require hatred, or ambition, or consciousness. It doesn’t even require disobedience. It requires, simply, a sufficiently powerful machine, inadequate instruction, and nobody recognizing the difference until it’s too late.



Leave a Reply